Automatically generated narration. Code examples are available in the article.
Project context
From November 2025, I worked in the SRE team on a Data Lake platform for a major Japanese telecom company. The wider platform was intended to collect and analyze real-time data at the scale of roughly 90 million users.
The overall project involved about 300 people across multiple teams. My responsibility was the infrastructure for the Data Lake module, not the entire platform. Specialist teams provided the architecture and security designs.
My work
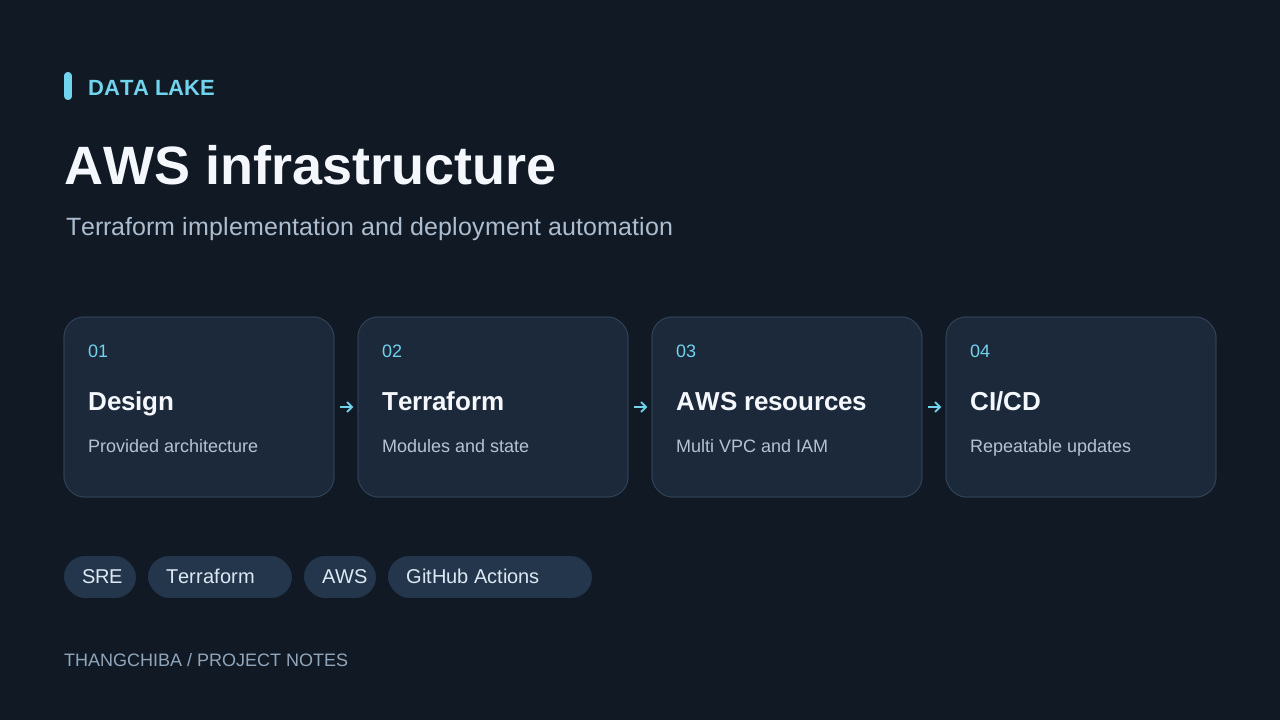
I translated those designs into Terraform code, provisioned and checked AWS resources, and worked on CI/CD pipelines. The implementation needed to account for differences between environments and fit with existing resources.
In the Multi VPC setup, I checked service communication paths, VPC Peering and PrivateLink connections, Security Groups, and Route Tables. I also worked with IAM permissions, KMS, and Secrets Manager to implement the supplied security requirements.
For deployment automation, I used GitHub Actions and AWS CodePipeline / CodeBuild. The work included pipelines for Lambda, ECR, and processes related to MSK and Aurora, with the goal of making environment setup and updates repeatable.
What I learned
This was an opportunity to work within a large, specialized project rather than own every design decision. I learned more about Terraform state, module reuse, environment differences, and how networking and permissions affect day-to-day infrastructure work.
The user count describes the scale of the overall project requirements. It is not a benchmark of infrastructure I built independently.
Role: SRE · Period: November 2025 onward, as recorded in my May 2026 CV.